Common Demandware SEO pitfalls and how to fix them
Today, Salesforce sells its commerce products as Agentforce Commerce. Yet most of us still call the platform Demandware (or SFCC). Whatever name you use, it remains a leading enterprise e-commerce solution for large retail brands, and in our experience, its public SEO documentation is still thin.
It’s typically licensed for larger retail programmes, so engineering access is often gated. That’s why platform-specific audit patterns matter.
The brand name may have changed from Demandware to SFCC after Salesforce’s 2016 acquisition, but it remains a core enterprise retail platform, and many storefronts still use legacy Demandware URLs and template patterns. Those patterns are the focus of our Salesforce Commerce Cloud technical SEO work that this guide covers.
If you’re on the client side and are looking to use SFCC for your e-commerce platform, factor in the cost of hiring an in-house developer or training someone to tweak and work on the site. Given the investment involved, it’s understandable that access to the platform is restricted and there is a lack of SEO documentation about the platform.
At SALT, we’ve been privileged to work with many international SEO clients who use SFCC, so it makes sense to share some common pitfalls and how to fix them from our experience. Below are the SFCC (formerly Demandware) technical SEO patterns we still remediate on enterprise retail builds: crawl paths, refinements, soft 404s, redirects, and international architecture.
Crawl and indexing
URL structure
If you regularly work on Demandware websites, you’ll know they’re easy to spot from their URL structure, especially the specific folder structure of /on/demandware.store/Sites-yoursite-Site/default/.
This folder structure is generally innocuous as it’s largely used for user information or hygiene pages such as account, password, wishlist, store finder, and gift certificate pages. In most cases, you don’t need to do anything about it. However, one or two folders usually need consolidation either to the homepage or to other relevant pages.
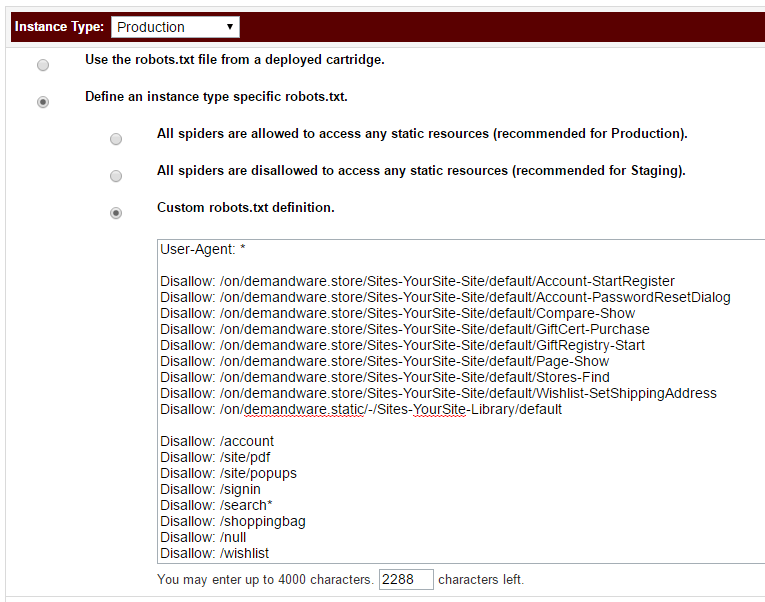
However, to optimise crawl efficiency, save crawl budget, and keep the site’s index tidy, we’ve blocked the folder structure from crawling and indexing in the robots.txt file. Before you decide to block it in your robots.txt, you should know the purpose of each folder and get the full list of respective sub-folders that reside within this folder structure from Screaming Frog.
Double or even triple-check the folder that contains JS or CSS files, as disallowing that folder might affect how Googlebot renders other pages. To check, run a few key templates through the URL Inspection tool in Search Console and look at the rendered HTML and screenshot. If product content or navigation is missing, a blocked folder might be the cause.
(blocking hygiene pages from crawling and indexing in robots.txt)
Top tip:
Ensure your URLs don’t contain special characters, as this can create issues with the canonical link of the page. During a routine technical SEO audit that we performed for one of our clients, we discovered thousands of 404 pages with a ‘null’ string at the end of URLs. After some investigation, we learnt that these URLs were actually canonical URLs from product pages that contained special characters in the URL. In our client’s case it was quotes within the URL. This then resulted in the canonical URL equating to ‘null’ due to malfunctioning backend code and creating thousands of 404 pages as shown below:
How we’ve resolved this:
Set your site’s URL configuration through SFCC’s URL Rules module. You can do this in Business Manager by going to:
- Merchant Tools > SEO > URL Rules
- Select the ‘Settings’ tab, and click ‘Edit Rules’.
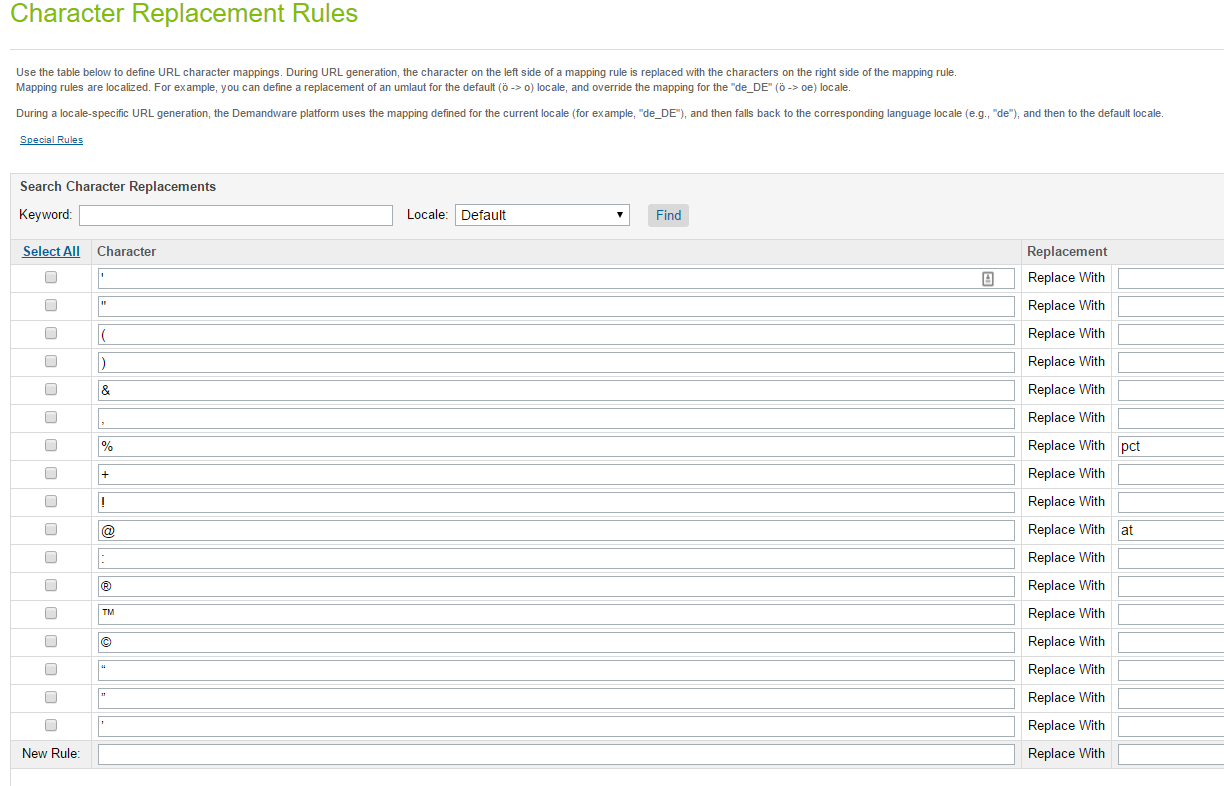
The same module controls character replacement for case, white space, and custom characters across category, folder, and search refinement URLs. Test changes in a sandbox before replicating them to staging and production.
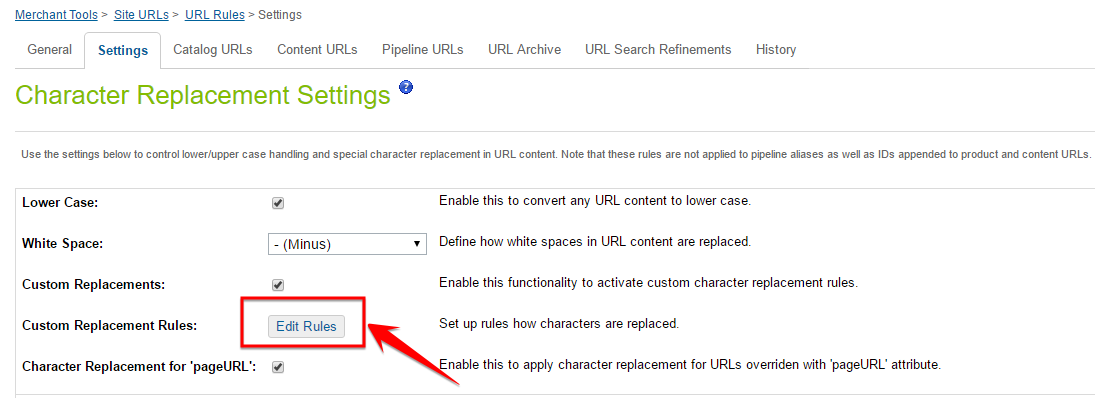
You can replace all special characters with blank so that it creates user-friendly and meaningful URLs, which in turn also resolves the canonical URL configuration issues. Once the rules are in place, re-check canonical consistency in your next technical audit.
Robots.txt for Demandware (dev, staging, production)
By default, the robots.txt file for Development and Staging on Demandware is set to block all crawlers from accessing static resources, while for Production, it’s set to allow crawlers to access all pages.
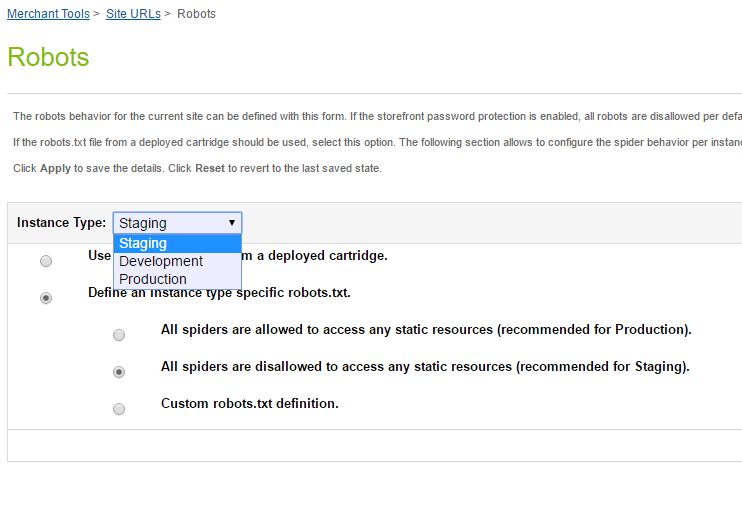
However, you can customise the robots.txt file:
- Go to Merchant Tools > SEO > Robots
- Select Define robots.txt Specific to Instance Type
- Choose a custom robots.txt definition.
Salesforce’s Trailhead guidance is to create the file on staging and then replicate site preferences to production. Business Manager allows up to 50,000 characters:
As your business grows, your products and catalogues follow suit, or vice versa. This also impacts the number of user information or other hygiene pages, as well as category and product pages being created. Add product refinement to that or faceted navigation, where each product variation creates a URL with parameters.
Also add customised landing pages for your paid campaigns with all the UTMs and top it with international SEO country edition folders. Before you know it, you have a colossal website in which the crawling and indexing can easily spiral out of control. There’s also the risk of duplicate content.
A customised robots.txt file is crucial for managing your crawl budget and index rate. Because SFCC is fully hosted, you won’t be pulling logs off your own web server. The platform’s embedded CDN (eCDN) is the workaround: Salesforce says eCDN logs can be downloaded from Business Manager for up to seven days or sent to your own Amazon S3 bucket with eCDN Logpush.
Since the 25.10 release, eCDN error logs also appear in Log Center. Until you have that set up, robots rules, crawl diagnostics, and parameter control carry extra weight. Where you can get logs, our beginner’s guide explains how we approach log file analysis.
URLs with parameters
URLs with parameters are a common SEO risk on e-commerce platforms. On SFCC they mostly come from product refinements and faceted navigation.
Google is clear about the scale of the problem. December 2024 guidance from Google said faceted navigation is the most common source of overcrawling site owners report. It advises disallowing faceted URLs in robots.txt if you don’t need them indexed. When you need them indexed, use standard & separators, keep filters in a consistent order, and return a 404 for filter combinations with no results.
SFCC gives you a second option for the refinements you want indexed. URL Rules can map enabled search refinements into the URL path instead of parameters, so a page like /womens/dresses/blue/ can rank as a clean category URL.
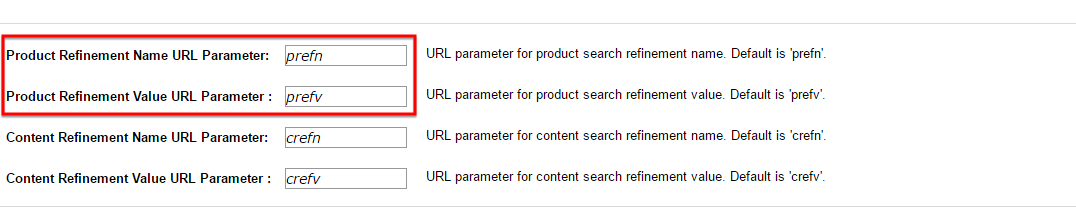
By default, product refinement on Demandware generates query strings of ‘prefn’ and ‘prefv’, so when you’re doing your regular site crawl with Screaming Frog, keep an eye on these two. Even though in most cases, these URLs with parameters are self-canonicalised to the primary URL, on many SFCC catalogues we still constrain prefn and prefv refinement URLs in robots.txt after mapping each folder’s purpose. We pair that with clear canonicals and internal-link control, as Disallow alone doesn’t always stop URLs being discovered or appearing in search results. A quick site: search on Google will tell you that:
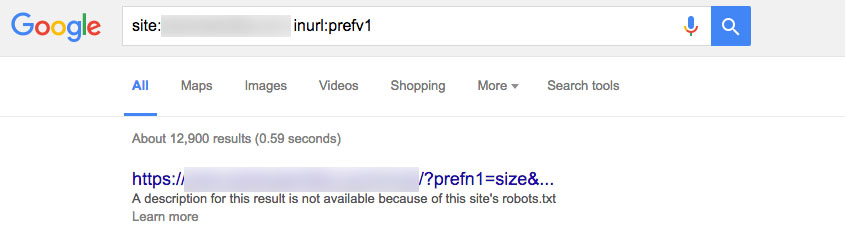
If your site has internal search and faceted navigation, plan how you handle these parameters carefully.
Tom Bennet has produced a solid, in-depth article in which, in one section, he goes into detail about preventing search engines from discovering specific content on your website using various approaches. He further adds that the aims are twofold: to prevent these URLs from showing up in organic search results and to optimise crawl budget. Oliver Mason also did some testing on pairing Noindex with Disallow directives in robots.txt to get the indexed pages dropped out of Google index.
However, Google stopped supporting noindex in robots.txt on 1 September 2019, so that pairing no longer works.
Today, choose one path. Either let a URL be crawled and give it a noindex robots meta tag or X-Robots-Tag header or block it with Disallow. Don’t do both, because Google can’t see a noindex on a page it isn’t allowed to crawl. The mid-2016 pairing below is historical only and shows what we did at the time:
We implemented it in mid-May 2016 and, after tightening parameter discovery, Search Console crawl stats trended down over the following months. Treat this as a historical pattern and re-baseline on any live build:
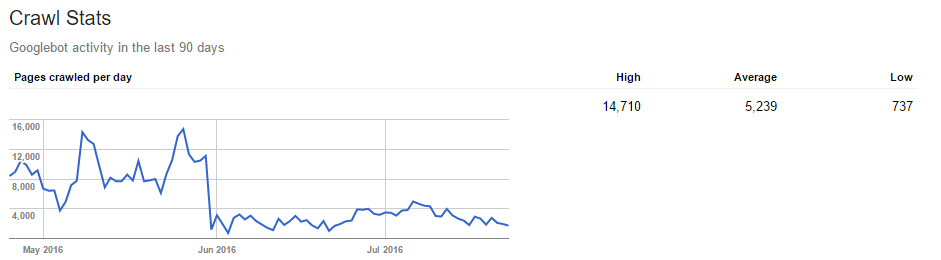
Parameter volume in Google’s URL Parameters report also roughly halved over the course of that engagement. Google has since retired that tool, though. Today, re-validate parameter handling with current crawl data and index coverage reports instead.
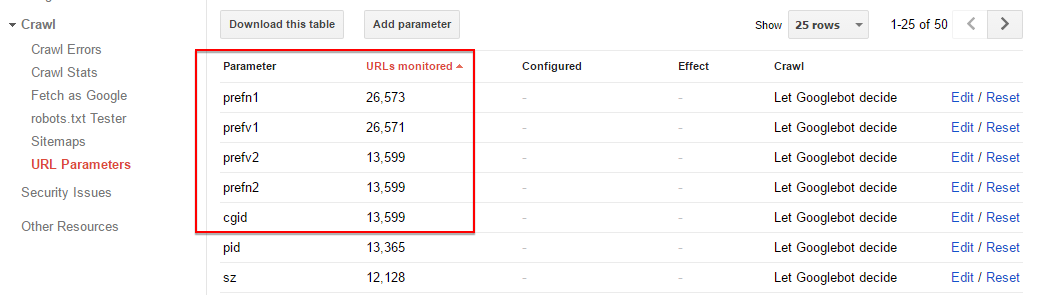
Whichever approach you implement, you need to control how these parameters might affect your site’s crawl efficiency and the risk of duplicate content.
404s and soft 404s
Seasonal product and category removals mean genuine 404 and 410 responses are normal on an e-commerce website. What matters is that pages return the correct status code and that your custom 404 page is useful.
You still need to keep an eye on the number of 404 pages in the Not found (404) section of Search Console’s Page indexing report and make sure the trend is heading down. Don’t redirect every 404, though. If there’s no equivalent content to send people to, leave it as a 404 or a 410. Save 301 redirects for URLs with links or other quality signals worth consolidating.
The problem comes when your custom 404 error page returns a 200 status code, instead of a 404 status code. Googlebot crawls the page and flags it as a soft 404 page. In general, soft 404s occur when content on a page is an error page yet it’s showing 200, or content on a page is minimal and looks like an error page yet the page is showing a 200 status code. It can also happen when content on a page is irrelevant to the original page (when a redirect is in place), especially when implementing a catch all redirect to the homepage/category page.
Google flags soft 404s because they’re bad for user experience. They also waste crawl budget, as Googlebot keeps trying to crawl and index pages that don’t exist.
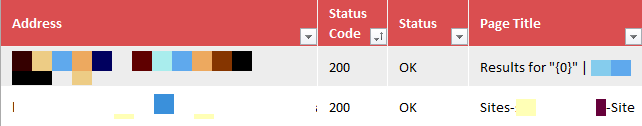
On Demandware, you can spot soft 404 pages from a specific pattern on the page title. In Screaming Frog’s crawl result, the page titles would look something like:
How we’ve resolved this:
- Determine if it’s worth your time to redirect the 404 pages or just serve a 404 page (effort/time vs. reward)
- Ensure that the custom 404 error page serves a 404 status code and the page conveys a clear message to the user that the page no longer exists plus some relevant links / search box to retain user on your site. Our guide to custom 404 and soft 404 handling covers this in more detail.
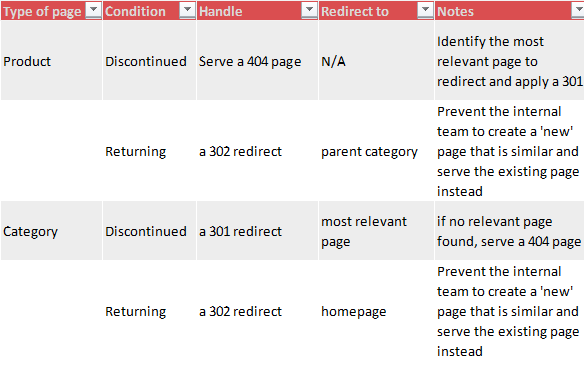
What we’d like to build next: develop a redirect functionality in the backend to handle different types of pages:
International SEO: multi-brand and multi-site builds
This isn’t a common pitfall, but it’s hard to undo after launch, so it’s worth getting right early.
When using Demandware for international web builds, build SEO in from the start, so that the international versions of your site reside on the same codebase. In Demandware, you can share code between multiple Demandware sites with Master Architecture.
In essence, Master Architecture means that there’s a core part of the codebase that applies to all or most of your sites. All site-specific styles and functionality are layered on top of that. The core part of the codebase will contain all the shared features common to the multiple sites.
In one of our post site-migration audits that we performed for one of our clients, after they were migrating 10 European country TLDs to the .com TLD, we stumbled on an hreflang issue. When the US and European codebases were stitched together, hreflang between the .com and the country editions failed to associate equivalent products.
For example, a product page from the EN-US version wasn’t associated with the same page on the FR-FR or EN-GB versions. Google treated them as separate, competing pages. The European pairs, such as EN-GB and DE-DE, alternated just fine.
The client development team had built a different codebase for the US and the rest of the international websites. Google didn’t recognise the cross-codebase alternates until the architecture and hreflang were aligned, and it took Google several months to understand the relationship between the country and language editions. If you face a similar issue, read about a fix in our guide to hreflang x-default and alternate association.
The earlier you plan for international SEO, the stronger the foundations of your SFCC strategy. That often means agreeing on SEO requirements before development planning starts. Our approach to international hreflang and multi-site architecture starts at exactly that planning stage.
Headless builds: Composable Storefront and Storefront Next
SFCC builds can also run headless, on Composable Storefront (built on PWA Kit and hosted on Managed Runtime) or the newer Storefront Next. All checks in this guide still apply, but add one more: confirm that the HTML Google receives already contains your canonical tags, hreflang, product copy, and internal links, rather than relying on client-side JavaScript to add them.
The URL Inspection tool’s rendered HTML is the quickest way to check. Managed Runtime logs are also available in the Log Center when you need to trace a rendering error.
Quick SEO wins for existing Demandware sites
Quick win #1: a best practice document
Write a short document covering on-page SEO best practices and what to do when a product or category page is about to be removed. It sounds basic, but making sure the internal team knows the process saves hours of rework.
Quick win #2: URL redirects vs. static mapping
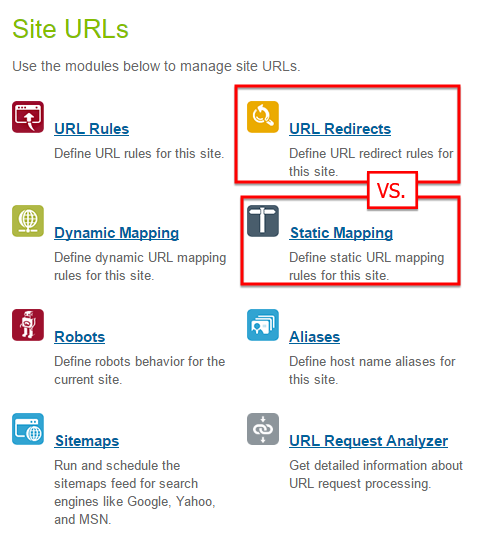
If you’ve got tonnes of 404 pages, you can use static and dynamic mappings (Merchant Tools > SEO > URL Redirects) instead of page-by-page URL redirects. Use static mappings for one-off URLs and dynamic mappings for patterns, such as a whole retired category.
According to Trailhead, each site can hold up to 50,000 URL redirects and around 18,000 static and 18,000 dynamic mappings. Salesforce’s documentation also notes that static mappings need a hostname alias configured first, and that the Business Manager configuration is capped at 2 MB, so larger sets go in through site import.
The way we did this was to put together a master spreadsheet containing all the 404 pages from all possible sources such as Search Console, Ahrefs, and Majestic, merge and purge the dupes and put a priority scale on which pages to redirect based on whichever metric you want. It could be the number of individual links pointing to the page, no. of linking root domains, social shares or any other relevant metrics. If you have thousands and thousands of 404 pages or want to fix broken links pointing to your domain to retain the equity, static mappings are the quickest route.
Using Screaming Frog, make sure to fetch all the 404 pages’ relevant information such as status header, new redirect URIs, etc. before you are working on the 301 redirect. If the page has somehow been redirected to a new URI using a 302 redirect, then replace it using a 301 redirect instead. Also check for the redirect chain report from Screaming Frog to minimise the impact of link equity loss from the redirect loops. Getting these details right protects your link equity over time.
Quick win #3: Core Web Vitals (CWV)
Minify the output code and remove unnecessary characters from the source code like whitespace, comments, etc. A reduction in source file sizes means a lower amount of data that needs to be transferred to the site’s visitors, and this in turn improves page load time/site performance.
Also, double-check the source code for a large number of inline JS/CSS/Base64. Unless necessary and unique, this code should be served async/from external files so that it can be correctly cached, reducing page load times and improving page load speed/site performance. Then prioritise by template rather than page-by-page.
Google Analytics’ old Site Speed reports went with Universal Analytics, so use the CWV report in Search Console to see which templates (product, category, search) fail. Then use PageSpeed Insights to diagnose them. Since March 2024, Interaction to Next Paint (INP) has replaced First Input Delay as the responsiveness metric. On SFCC category pages, check refinement and filter scripts first.
If you’re auditing an SFCC site, start by checking the answers to these five questions
- What does your production robots.txt block?
- How many prefn and prefv URLs is Google crawling?
- Does your custom 404 page return a 404?
- Do hreflang pairs match across every locale?
- Is eCDN Logpush switched on?
If you’d like help with any of them, get in touch.


